What Is a Discriminative Model in AI? Definition, Examples & Uses
What is discriminative model in AI? It is a system that separates classes and predicts labels from input features. The discriminative model definition centers on learning differences between classes. In discriminative machine learning, models can decide whether an email is spam or spot disease signs in medical images.
At their core, these models learn a decision rule or conditional probability. They estimate links between inputs and target outcomes, which supports effective classification tasks. This article explains how they work, differ from generative models, and use common algorithms.
We also examine AI classification models, practical applications, advantages, limits, and best practices. This overview helps readers assess AI methods for business or software development.
Key Takeaways
- Discriminative models excel at classifying data and predicting outcomes.
- They focus on learning decision rules based on input features.
- Understanding their differences from generative models is essential.
- Common algorithms include logistic regression and support vector machines.
- These models have practical applications across various industries.
What Is a Discriminative Model in AI?
A discriminative model definition describes how AI sorts inputs and predicts outcomes. These models learn AI decision boundaries between classes in data. They assign labels to inputs based on learned patterns.
Core Definition and Purpose
A discriminative model learns the link between input features and output labels. It predicts a label from input data without modeling how the data was created. Common uses include these tasks:
- Binary Classification: Assigning one of two possible labels to an input.
- Multiclass Classification: Assigning one label from multiple categories.
- Ranking or Scoring Tasks: Evaluating inputs based on a scoring system.
Role in Supervised Learning Frameworks
Discriminative models are key supervised learning models. They need labeled examples with input variables and known outcomes. The model estimates a function, such as \(y = f(x)\), from these examples.
It may also estimate conditional probability in machine learning, shown as \(P(y|x)\), to predict unseen outcomes.
Why Discriminative Models Matter in Modern AI
Discriminative models matter in modern AI because they support fast, high-volume prediction systems. They are widely used in:
- Automated decision-making processes
- Fraud detection and screening
- Recommendation systems
- Search engines and language processing
- Computer vision applications
Their direct focus on prediction often improves production performance compared with other approaches.
Related Posts:
| Model Type | Use Case | Advantages |
|---|---|---|
| Discriminative Models | Classification and Regression | High accuracy in predictions |
| Generative Models | Data Generation | Understanding data distribution |
How Discriminative Models Function in Machine Learning
Understanding how discriminative models work helps explain their role in machine learning. They separate classes by studying labeled training data. This section covers input features, the machine learning decision boundary, probability estimation, and direct classification.
The Learning Process Explained
The learning process for discriminative models begins with collecting labeled examples. These examples contain input features and their corresponding labels. Input features can vary widely, including:
- Numerical measurements (e.g., age, income)
- Categorical values (e.g., gender, occupation)
- Text tokens (e.g., words in a document)
- Pixels (e.g., in images)
- Audio signals (e.g., sound frequencies)
- Behavioral events (e.g., clicks on a website)
Each label shows an outcome, such as “approved,” “fraudulent,” “positive,” or “negative.” Feature quality, class balance, and label accuracy strongly affect model performance. Proper data preparation supports effective learning.
Input Features and Labeled Data
High-quality input features help models learn effectively. Poorly defined features or inaccurate labels can make predictions unreliable. Therefore, labeled training data must be representative and comprehensive.
Decision Boundary Formation
After training on labeled data, the model identifies a decision boundary in the feature space. This mathematical representation separates different classes. For example, consider simple email classification:
A model may separate legitimate emails from spam using:
- Sender information
- Message language
- Links included in the email
Linear models create simple decision boundaries. More complex models, such as tree-based methods and neural networks, capture detailed feature relationships.
Probability Estimation vs. Direct Classification
Discriminative models can be grouped by their output. Some provide class probabilities, while others directly assign labels or scores. Understanding this difference is crucial:
- Probability Estimation: Models output the likelihood of each class, allowing flexible decisions.
- Direct Classification: Models assign a label using a threshold. You can adjust it to prioritize precision or recall.
Adjusting the probability threshold can balance speed and risk control for each application. For example, in fraud detection, a lower threshold may reduce false negatives, while a higher threshold may improve overall accuracy.
Discriminative vs. Generative Models: Key Differences
Understanding discriminative vs. generative models helps with model selection in AI. Each approach has a different purpose and may produce different results for a given task.
Defining Generative Models for Context
Generative models learn the underlying data distribution, often shown as joint probability P(x,y). They can create new examples or infer missing information from learned patterns. Generative AI models commonly support these tasks:
- Language generation
- Image synthesis
- Data augmentation
- Probabilistic modeling
Core Mathematical and Conceptual Differences
Discriminative models usually learn conditional probability P(y|x) or a direct decision function. Generative models describe how inputs and labels form together. These differences affect model choice:
| Aspect | Discriminative Models | Generative Models |
|---|---|---|
| Objective | Learn P(y|x) | Learn P(x,y) |
| Data Requirements | Requires labeled data | Can work with unlabeled data |
| Computational Cost | Generally lower | Often higher due to complexity |
| Interpretability | More interpretable | Less interpretable |
When to Choose Each Modeling Approach
Choose between discriminative and generative methods based on your project’s goals. Discriminative methods work best when accurate predictions from available inputs matter most. Generative methods excel at tasks such as:
- Content creation
- Simulation
- Density estimation
- Missing-data reconstruction
- Unsupervised learning
Hybrid systems combine both approaches and use each model’s strengths. They can provide a more complete solution.
Common Algorithms Used in Discriminative Modeling
Discriminative modeling uses algorithms with different strengths and uses. Knowing these methods helps people choose tools for many tasks. Common choices include logistic regression, support vector machines, decision trees, random forests, and neural networks.
Logistic Regression
Logistic regression estimates class probabilities. It works best for binary classification but can also handle multiclass problems. Logistic regression classification works well when feature and class links are simple, and its clear results are easy to explain.
Support Vector Machines (SVM)
The support vector machine algorithm finds a separating hyperplane with the widest margin between classes. It suits small and medium-sized datasets with well-designed features. SVM can use kernel functions for nonlinear relationships, making it useful for many classification tasks.
Decision Trees and Random Forests
Decision trees make sequential, feature-based decisions to classify data. They are intuitive and easy to visualize, but they may overfit. To reduce overfitting, random forests combine trees; this random forest classifier improves stability and accuracy.
This ensemble suits structured business data and mixed features, with strong performance across many situations.
Neural Networks and Deep Learning Architectures
Neural networks are powerful discriminative models, especially with deep learning. These layered systems learn increasingly complex patterns from raw or minimally processed data. Neural network classification supports image recognition, speech processing, and natural-language tasks but needs sufficient data, computing power, and careful validation.
In summary, each of these discriminative modeling algorithms has strengths and weaknesses. Choose based on task needs, including data size, complexity, and the need for interpretability. For further insights, explore discriminative models and their applications in various domains.
Those interested in deep learning models can find a beginner’s guide here.
Real-World Examples of Discriminative Models
Discriminative models support many daily applications. They help technology make useful choices faster and more efficiently. These discriminative model examples show how they work in real life.
Email Spam Detection Systems
Email spam detection systems use discriminative models to label messages as spam or legitimate. These systems use sender reputation, message content, embedded links, attachments, and user behavior. This approach supports spam detection machine learning by assigning each email a spam probability.
These systems need regular retraining to stay effective. Spammers often change tactics to avoid detection. Regular updates help organizations keep their spam filters strong and reliable.
Image and Facial Recognition
In computer vision, facial recognition AI uses discriminative models to identify and classify visual patterns. It compares facial embeddings with known identities for accurate recognition. Uses include security systems and social media tagging.
These models depend heavily on high-quality training data. Representative datasets should include diverse demographic groups to reduce bias. Privacy protections and human oversight support ethical use of facial recognition technologies.
Medical Diagnosis Applications
Discriminative models also support machine learning medical diagnosis. They classify medical images, estimate disease risks, and find patterns in patient records and laboratory results. These insights can help clinicians make better decisions about patient care.
These systems can support qualified professionals, but they should not replace them. Validation, transparency, and regulatory compliance help these tools work safely and effectively. Proper handling of false positives and negatives remains crucial in medical contexts.
Practical Applications Across Industries
Across industries, discriminative models improve efficiency and support better decisions. They are changing healthcare, finance, natural language processing, and computer vision.
Healthcare and Clinical Diagnostics
In healthcare, discriminative models support healthcare machine learning and several important applications.
- Patient risk stratification
- Clinical decision support
- Triage and medical imaging
- Readmission prediction
- Treatment-response classification
Medical use requires careful validation, secure data handling, and fairness testing. These models must also fit smoothly into clinical workflows.
Finance and Fraud Detection
In finance, fraud detection models support several important tasks.
- Credit risk assessment
- Transaction monitoring
- Identity verification
- Anti-money-laundering alerts
- Insurance claims analysis
These models track changing fraud patterns and help institutions follow regulations. They also reduce costs from unnecessary investigations.
Natural Language Processing Tasks
Discriminative models support many natural language processing (NLP) tasks.
- Sentiment analysis
- Intent detection
- Topic classification
- Toxicity detection
- Document routing
- Named entity recognition
- Email or ticket prioritization
These uses show the flexibility of NLP classification. They improve communication and information retrieval.
Computer Vision and Autonomous Systems
Computer vision and autonomous systems AI support several important applications.
- Object detection
- Lane recognition
- Quality inspection
- Robotics
- Security monitoring
- Autonomous navigation
Successful deployment requires strong predictions and low latency. It also requires scalability, explainability, reliability, and safety.
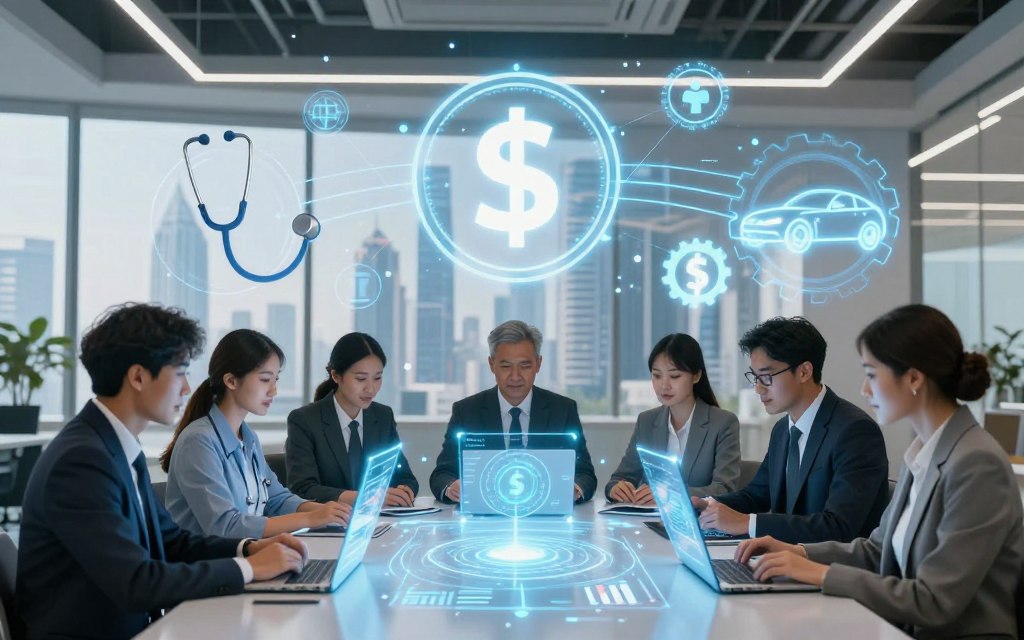
These AI applications by industry show how discriminative models improve innovation and efficiency. As technology advances, these models may become more important across sectors.
Advantages and Limitations of Discriminative Models
Discriminative models have clear strengths and limits that shape their use in AI applications. Knowing these points supports better choices during deployment.
Key Strengths in Production Environments
One of the primary advantages of discriminative models is their direct focus on prediction. They perform well in supervised tasks and support strong metrics for production AI systems. They also make efficient inferences for real-time applications.
Discriminative models handle structured and unstructured data, so they work across many fields. They suit automated decision pipelines that need fast, accurate predictions. Many can produce calibrated probabilities, rankings, or confidence scores for operational workflows.
Notable Limitations and Trade-offs
Despite these strengths, discriminative models have notable limits. They rely on high-quality labeled data, which creates barriers in many situations. They also respond poorly to distribution shifts in changing environments.
These issues reflect wider limitations of machine learning. Unlike generative models, discriminative models mainly distinguish classes, which limits creative uses. Also, model bias and overfitting may cause strong training results but weak results on new data.
Common Challenges in Real-World Deployment
Real-world deployment brings several challenges for discriminative models. Class imbalance, noisy labels, and missing data can reduce model performance. Teams must address bias, privacy, and adversarial behavior for ethical use.
Infrastructure costs and latency can hinder implementation. Continuous monitoring helps manage AI deployment challenges, such as model drift and integration with existing systems. Accuracy alone is not enough; responsible use needs governance, documentation, security controls, and ongoing human review.
| Aspect | Advantages | Limitations |
|---|---|---|
| Focus | Directly predicts outcomes | Dependent on high-quality labeled data |
| Performance | Strong in supervised tasks | Sensitive to distribution shifts |
| Data Compatibility | Works with structured and unstructured data | Limited content generation ability |
| Operational Use | Efficient inference for real-time applications | Risk of model bias and overfitting |
“Understanding the strengths and challenges of discriminative models provides insight into their role in AI.”
For a deeper dive into the differences between discriminative and generative models, check out this resource.
Best Practices for Implementing Discriminative Models
These discriminative model best practices can improve performance. A structured process helps teams build models that meet their goals. Key steps include data preparation, model selection, hyperparameter tuning, and evaluation metrics.
Data Preparation and Feature Engineering
Data preparation is the first key step in implementing discriminative models. Begin by clearly defining the prediction target. This clarity keeps each later step aligned with the intended outcome.
Collect representative data that accurately reflects the problem space. Remove duplicates and address missing values to protect data integrity. Encode categorical variables and scale numerical features to improve performance.
Also, prevent data leakage because it can skew results.
Feature engineering techniques should use domain knowledge and avoid unavailable prediction-time variables. This approach keeps the model practical for real-world use.
Model Selection and Hyperparameter Tuning
Start with a simple baseline model before testing complex algorithms. This baseline provides a reference for measuring improvements.
When choosing models, consider accuracy, interpretability, latency, data volume, and maintenance needs.
Hyperparameter tuning is crucial for improving model performance. Grid search, randomized search, and Bayesian optimization can help find the best parameters. Important choices include regularization strength, tree depth, learning rate, class weights, and threshold settings.
Evaluation Metrics and Validation Strategies
Use a range of model evaluation metrics because accuracy alone can mislead, especially with imbalanced classes. Precision, recall, F1 score, specificity, ROC-AUC, PR-AUC, and log loss show performance more fully.
For cross-validation machine learning tasks, use train-validation-test splits and stratified cross-validation. Use temporal validation for time-dependent data. Subgroup analysis and stress testing also help ensure robustness.
Post-deployment monitoring is essential for maintaining performance over time. These discriminative model best practices help teams deliver reliable, actionable insights.
Conclusion
Discriminative models in AI help distinguish classes or predict outcomes from input data. Unlike generative models, they learn from labeled examples within supervised learning frameworks. They set decision boundaries or estimate conditional probabilities, which makes them useful in many applications.
Healthcare, finance, and cybersecurity industries benefit greatly from these models. Medical diagnostics use them to predict patient outcomes, while finance uses them to detect fraud. The field of machine learning classification continues to evolve.
Logistic regression, support vector machines, random forests, and neural networks each have unique advantages and challenges. Organizations must consider interpretability, scalability, and data requirements during AI model selection.
Looking ahead, the future of discriminative learning is promising. As technology advances, validating models with suitable metrics will become more important. Post-deployment monitoring helps address fairness, privacy, and model drift.
By focusing on reliable predictions, businesses can use discriminative models to improve operations and drive innovation.